Google Backup and Sync: That syncing feeling


Andy Webb
K.G. Orphanides

27 Mar, 2020

A capable file-sync tool, but it’s no backup behemoth

Price 
£4

If your business uses G-Suite, then good news: you’re already subscribing to a cloud-based backup and synchronisation solution. How much capacity each user gets depends on your G-Suite subscription level. The G-Suite Basic tier has 30GB by default, with higher tiers providing unlimited storage and various options to individually upgrade a user’s drive to 100GB or 1TB.

Like Microsoft’s OneDrive-based cloud storage and other syncing-oriented services, it can be extremely useful if you or your corporate users want to access their files from multiple computers, or simply have all their work to hand when they move to a new workstation.

Google’s Backup and Sync tool works the same for business and home users, although the G-Suite version includes granular admin tools to enable features such as filestream – the ability to stream, rather than sync, G-Suite content – and offline access.

At install time, you’re prompted to choose which folders you want to back up and whether you’d rather have images and videos automatically compressed – for free storage – or left at their original quality. Other options here allow users to set upload and download speed limits, proxy settings and set specific file types to be excluded from their backups.

Note that, since July 2019, photos and videos are no longer made available via Google Drive, but instead can only be accessed through the Google Photos interface, although both Drive and uncompressed Photos content both still count towards your storage allowance. 

You’re then asked to choose whether you want to sync everything that’s already in your Google Drive, to copy nothing to the local hard disk, or to sync only selected folders. You can also change the default path of your Google Drive folder.

Once installed, users can dig through the advanced settings to have the application automatically back up files from connected cameras, SD cards and USB devices, and to configure it to automatically delete or retain synchronised copies of removed files.

The backup side of the utility is a more recent addition, but once again, it’s online only. You can’t use the Google Backup and Sync utility to backup data to your network or external storage media, even as an additional feature.

Whatever folders you’ve opted to back up – all the user’s files by default – are automatically copied to cloud storage, where their contents can be browsed and accessed online via the ‘Computers’ tab in the Grive web interface. 

Unlike your main Google Drive, where data is kept in sync between all connected devices, every computer the user adds gets a dedicated entry here. The folder structure is retained and there are no granular features to control whether or not specific file types are included in your backup.

You can’t schedule backups, but any files that change are instantly uploaded if you have an internet connection, or synced in bulk when you’re next online. By default, 100 versions of a file are saved, but you can manually switch particularly important files to unlimited versioning.

Note that the Backup and Sync application won’t let you back up your entire user space, let alone your entire computer. Your OS and software are beyond the scope of this one, even if you have the kind of internet connection that makes fully cloud-based backups a realistic prospect.

File recovery is a matter of re-downloading any lost files or old versions that you might need. You can download an entire system archive and move files from an old system to a newly-installed system’s synced folders, but this isn’t as smooth as the targeted recovery tools you’ll find in many more fully-featured backup utilities.

Google Drive is an excellent syncing tool and G-Suite using businesses will almost certainly want to have their users’ data synced – although those dealing with sensitive customer and financial data should restrict these files and consider using a private storage solution.

But despite having ‘Backup’ in the name, if you want any kind of disaster recovery protection, you’re probably still going to need a more sophisticated backup tool to work alongside Google Drive’s very capable file synchronisation.

How to migrate your SMB network to the cloud


Andy Webb
K.G. Orphanides

26 Mar, 2020

So, the time has finally come. You migrated the office email to the cloud and the Exchange servers now sit forlorn in the corner of the IT room, collecting dust and half-finished cups of coffee. Then you moved the files to the cloud, and listened to the whine of the file server’s disk array fade away for the last time.

But the domain controller is still there in the rack, the last beacon of hum amongst the windowless desolation of loose carpet tiles and unidentifiable cables that is the server room. All that shiny new cloud infrastructure depends on this last server, home to your Active Directory and the photos of the 2008 office party. It’s time to migrate this vestige to the cloud as well and let silence fall in the server room.

Starting point

In this tutorial, we’ll be looking at a small business setup, comprising a single server running ESXi, hosting a single Windows Server 2012r2 virtual machine which is acting as domain controller and file server, and a firewall/router capable of maintaining an IPSec VPN link to the cloud. The ESXi box needs enough spare disk space to install the Azure Site Recovery (ASR) appliance image to handle the migration. We will be using a PFSense firewall, but any decent business firewall/router should be OK, such as Cisco ASA, Checkpoint, Sonicwall and so on.

We’ll be using Microsoft Azure for this tutorial: the specifics of the migration process vary between various cloud providers, so you’ll also need to use Azure. We assume for the purposes of this tutorial that you’ve already created an Azure account, chosen a region and set up a resource group. Whilst this can be done in almost all Azure regions, you need to set everything up in the same region for this to work.

Our starting network is laid out as follows:

Subnet – 10.10.12.0/24

Server – 10.10.12.50

Firewall – 10.10.12.10

DHCP range – 10.10.12.100-200

ESXi server 10.10.12.5

Domain – smeoffice.local

Step 1: Virtual network setup

The first thing to do is to set up a virtual network for the cloud server to connect to. In the Azure portal, click on “Create a resource” at the top of the left hand menu bar, and then select the Networking category and choose Virtual network from the top of the right hand menu. Choose an address space, and a subnet within it, and select the appropriate resource group from the pull-down menu. We used 10.20.0.0/16 for the address space, and 10.20.1.0/24 for the subnet.

Step 2: Set up a Virtual Network Gateway for the cloud network

Next, we need to set up a Virtual Network Gateway for the cloud subnet. This will act as the cloud end of a VPN tunnel from the office to the cloud subnet. Go back to the Azure portal home screen using the menu on the left, and click on “Create a resource” again. Type “Virtual network gateway” into the search box and select it from the drop-down menu.

Click on Create, then give the gateway a name. There are several types of VPN gateway available, with different pricing models. We’ll be using the basic, cheapest option. Select this from the drop-down SKU menu, then select the virtual network we just created from the Virtual network dropdown menu. Enter a name for the public IP address and leave everything else on the defaults.

Now click on Review + create at the bottom of the page. If everything looks OK on the next page, hit the Create button at the bottom of the page. This deployment may take a while, so now is a good time to make a cup of coffee or write a novel.

Step 3: Create a local network gateway 

Now we need to create a local network gateway in Azure to represent your office firewall or router. Click on Create a resource, type “local network gateway» into the search bar and select it from the menu as before. 

Click on Create, then give it a name and fill in the office subnet details and the public IP address of the firewall. Select the appropriate subscription and resource group, then click on create.

Step 4: Create a site-to-site VPN from the office to the cloud subnet

We can now create the VPN link between the new cloud subnet and the existing office subnet. Select all resources from the left hand menu, then locate your virtual network gateway on the list and select it. Click on connections, then on the add button.

Name your connection, and select site-to-site from the drop-down connection type menu. Select your local gateway from the list, and provide a shared key for the VPN. Now click OK.

Now we just need to configure the office end of this VPN on your office firewall or router. Don’t forget to add appropriate firewall rules to allow traffic across the link between your office and the cloud subnet.

Step 5: Set up a recovery services vault

In the Azure portal, click on create a resource again, then type «recovery» into the search box. Select backup and site recovery from the list, then click on create. Name your recovery services vault and select the appropriate resource group and region, then click on review + create. Check the details and click on create.

Step 6: Configure the vault and deploy the site recovery server image

From the list of resources, select the vault we just created. Click on getting started in the site recovery column on the overview screen. Now click on prepare infrastructure. Answer the protection goal questions. You’ll be prompted to use Azure Migrate instead.

Right now, we still recommend using Azure Site Recovery (ASR) for this process, as Azure Migrate v2, released in July 2019, is still relatively new and a wider range of support and information resources are available for ASR if you encounter any snags or have any unusual use cases.   Tick the box to bypass Migrate, answer the last question and click on OK. 

Next is the deployment planner. Whilst Microsoft recommends running this tool, it’s largely designed to calculate the required bandwidth for regular replication of your on-site systems to Azure. As we’ll be using this for a one-off migration, you can safely skip this step. Select “I will do it later” from the menu and click OK to move on to the next stage.

Click on the add configuration server button, make sure that the server type is for VMware, then download the virtual machine template and import it into your ESXi server. It’s quite large so the download will take a while. The virtual machine image requires about 50GB of disk space on the ESX server to install.

Once the import is complete and the virtual machine has booted, connect to its console and accept the license terms, then on the next screen set a password for the local administrator account. You can allocate a static IP to this server at this point if you wish, but as it will only be required for a short time, it isn’t really necessary. 

Log in to the console of the ASR server using the password you just set. The ASR setup wizard will start, but before proceeding with that, open server manager and disable IE ESC, as it will cause irritation later in the process.

Step 7: ASR server configuration

Now you can move on to the ASR setup wizard. First, you need to set a name for this server to identify it in your Azure portal, then provide your Azure portal login so that the ASR server can register itself with Azure. 

If you have a multi-tenancy Azure setup, then you should provide an account associated with the target tenant, but if you have only the default tenant set up then you can use your root account login. Once the wizard has completed, the server will register itself with Azure, then reboot. 

Log in again and wait for the browser to open and display the ASR management page. Select the network interfaces for communication with the on-premises systems, and with Azure. As there is only one subnet in our office network, there is only one interface to choose. You can safely ignore the warning about using a dynamic IP, as this server is not going to be around for very long.

Save these settings, then click on continue to move on to the next page. Here, click on the sign-in link for Azure and tick the box to grant it the required permissions, then select the appropriate subscription and resource group, and the recovery services vault we created in step 5. Click continue to move on to the next stage.

Next, we install MySQL. Tick the box to accept the license, then click on the link to download and install MySQL. Once installation is complete, click continue to move on to configuration validation. Once this has completed, click continue. Once again you may safely ignore the warning about providing a static IP address and continue.

Step 8: Set up VMware and office server access

Now we need to provide the ASR server with the address and credentials for our VMware ESXi server, as well as an account with administrator-level access to the servers we wish to migrate to Azure. Click on the button to add the ESXi server and fill in your server details in the pop-up window.

Once you’ve filled those in, click on add, wait for them to be validated, then click on continue.

Click on the link to add VM credentials, then provide an administrator-level account for the domain controller. Click add and wait for validation, then click on continue followed by the last button to finalize the configuration. This will take a few minutes. Once it has completed successfully, you can log out of the ASR server console.

Step 9: Prepare the domain controller for migration

Now we need to prepare the domain controller for migration. Login to the domain controller and check for updates. Apply any outstanding updates, and reboot as necessary to ensure that there are no updates pending at the next boot.

Make sure remote connections to this server via RDP are enabled, and that they’re allowed through the firewall in all three profiles, otherwise you won’t be able to access the server remotely after the migration.

Step 10: Set up your replication source and destination

Go back to the Azure management portal, and select the vault we configured earlier. Click on getting started from the site recovery menu, then select prepare infrastructure. Check that the answers you provided in step 6 are still selected, then click OK. Skip the deployment planning as before, and move on to configure the source.

Select the configuration server and vSphere host that we set up from the available options. If you only have one configuration server set up and linked only to one vSphere or vCenter server, they will already have been selected. Then click on OK. On the next page select your Azure subscription, choose which deployment model you want, and click OK. We used the default resource manager model.

Lastly, we need to create a replication policy and associate it with the configuration server. Click on create and associate, enter a name for the policy and click on OK. The other options can be left on the defaults as we will be using this primarily for migration, not for regular snapshots or disaster recovery planning.

Wait for the creation processes to complete, then verify that the policy we just created is shown in the selection box, and click OK to close the policy creation window. Then click OK again to close the prepare infrastructure window and return to the vault administration page.

Step 11: Starting replication

Once started, the replication process will use a lot of internet bandwidth to perform the initial replication. You might want to perform this step outside office hours to avoid slowing down internet access for the users during working time.

To begin replication of the virtual machine to Azure, click on replicate application to open the enable replication setup. On the first page, check that the pre-filled values are correct, and select the configuration server we set up in step 7 as the process server. Click OK to move on to page two.

Once again, check the pre-filled answers are correct, then select your resource group, and choose the network and subnet we created in step 1 for the post-failover Azure network. Click OK to continue.

Select the VM to be migrated from the list of virtual machines on the next page. If you are migrating more than one VM, select them all here before clicking OK to continue. Set the type of disk you want for your VMs and choose the domain admin account we associated with the configuration server from the user account drop-down menu.

What type of disk you choose will depend on your usage patterns and on the costs associated with the disks. As everyone’s usage patterns are different, you will need to work this out for yourself – Microsoft provides tools to help estimate potential costs. Once you’ve made your choice, click on create target resources to continue.

Once the resource creation tasks have finished, check that the replication policy we created in the previous step is selected, and click on OK. We don’t need multi-VM consistency for this migration, but if you are migrating two or more servers that depend on each other, such as mirrored database servers, you may want to enable this. Now click on the enable replication button, and wait for the notification that replication has been enabled. This will take some time, as it needs to install the mobility agent on the target virtual machine and then prepare it for replication. For us it took about 12 minutes. Once this is complete, the initial replication will start.

How long this takes will depend on the amount of data to be moved and the speed of your office internet connection. To keep an eye on the progress, go back to the vault configuration page, select replicated items from the protected items section of the menu and click on the name of the VM in question.

Don’t worry if you get a warning that the initial replication has been flow controlled, as it is replicating a large amount of data this first time and unless you have an extremely fast upload speed, your host’s disks will be faster so will have to be throttled to prevent the configuration server running out of cache space. 

Step 12: Failover test

Before running the migration for real, it’s important to do a failover test to make sure that everything behaves as you expect it to. Once the initial replication has completed, select the vault, then click on replicated items in the menu. Select the virtual machine from the list on the right, then verify that its replication health is OK and that there are no warnings or issues that need to be resolved.

Select test failover from the menu bar, check to make sure that the time on the pre-selected recovery point is within the last hour and select the virtual network we created in step 1 from the drop-down menu. Now click OK to start the test failover running. This will take a few minutes. 

Once the test failover has completed, go back to the home page of the Azure portal and select virtual machines from the menu bar across the top. Select the failover test VM from the list. It’ll have the same name as your on-premises VM with “-test” appended to it. Verify that there are no errors showing and note down the private IP address assigned to it.

Now connect to that IP using your preferred RDP client and log in with your domain admin credentials. If you are unable to connect to the Azure VM, check that the VPN you set up in step 4 is connected.

Check that the server is running as you expected, and that all the services are OK. Once you are satisfied that all is well, disconnect from the server and go back to the Azure portal. Return to the vault page and the replicated items list, and select the server again. Click on cleanup test failover, tick the box to complete testing and click OK. This will remove the test VM and tidy everything up. Don’t leave the test VM running as it will incur costs.

Step 13: Migration time

In this step, we will shut down the on-site virtual machine and start up the Azure replica. As this will cause some downtime for your users, it should probably be done out of hours. This has the added benefit of minimising the likelihood of any changes to files or system state since the last replication point.

Go back to the vault screen and the list of replicated items. Select the virtual machine from the list, and verify that the replication is healthy and the current recovery point objective (RPO) is recent. If everything looks OK, click on failover from the top menu bar. Check the recovery point and tick the box to shut down the VM before beginning the failover, then click OK to start the failover task running.

Click on the notification bell towards the top right of the Azure portal and select the failover task. Monitor it to ensure that all the stages are completing successfully. Under some circumstances (generally relating to VMware licensing or version) it may fail to shut down the on-site VM, so you’ll need to do that manually once the replication has completed. This will not affect the failover process, however.

Once the failover process has completed, cleanly shut down the on-site virtual machine if it is still running, then go to the virtual machines section in the Azure portal and select the new VM created by the failover. Make a note of the private IP address that has been assigned to it.

Now we need to set up the DHCP service on the office firewall to take over from the server. Configure it to allocate the same pool of IP addresses as the server used, but set the DNS server option for DHCP clients to the private IP address of the new cloud VM. Remember to also re-create any static DHCP assignments that were present on the server. 

Refresh the DHCP leases on the office PCs (rebooting them is probably the quickest way), then test connectivity to the cloud VM by pinging it from one of the PCs, first by IP address then by name. Check that any mapped drives are working as expected, but be aware they will be slower than they were when the server was local, unless you have an extremely fast internet connection.

If everything looks fine from the client machines, connect to the server via RDP and check that everything is working as it should at that end. Pay special attention to the DNS zones on the server and make sure that the server’s old IP address has been updated to its new private IP in the forward lookup zones. Correct any remaining instances of the old IP address that you find.

Step 14: Final steps and tidying up

Return to the Azure portal, and to the list of replicated items in the recovery services vault. Select the virtual machine from the list. Ignore the replication errors, as those were caused when we shut down the VMware virtual machine in the office. Select complete migration from the menu bar and click OK to continue. This will disable the replication of the office virtual machine and tidy up the Azure site recovery setup. It’ll take a few minutes to complete.

Once that’s finished, return to the vault page and verify that the office VM is no longer listed on the replicated items page. If you have no further use for Azure Site Recovery at this time, you can delete the config and resources associated with it. 

From the vault page, select site recovery infrastructure, then on the next page select replication policies. Select the replication policy that we created in step 10, then click on the dots at the end of the line for the associated configuration server and select dissociate. Repeat this for the failback policy as well.

With that done, you should have fully and completely migrated your entire office infrastructure to the cloud. Welcome to the future.

Return to the list of replication policies, click on the dots at the end of the line for each of the policies we just dissociated, and select delete. Next select configuration servers from the vault menu, and select the config server from the list. Right click on the office ESX server and hit delete, then hit yes to confirm. Once that task has completed, click on delete on the upper menu bar to remove the ASR server and hit OK to confirm. Lastly, go back to the vault screen and select delete from the top menu bar, then hit yes on the next page to delete the recovery services vault.

Don’t forget to update the configuration for any devices in the office that do not obtain their IP addresses via DHCP to use the new IP address for DNS, and for any other services configured using the server’s IP address rather than its name.

Sipgate Team review: Cost-conscious cloud calling


Dave Mitchell

25 Mar, 2020

An affordable hosted service for small businesses, with flexible licensing plans and good call-handling features

Price 
£15 exc VAT

If you’re looking for a simple, practical, cloud-hosted VoIP service, Sipgate Team could be your perfect solution. It comes with a solid track-record too, as Sipgate has been going strong since 2004.

One reason it’s lasted so long is value. A Light contract starts at £14.95 per month for three users, and can be upgraded in small increments, so your VoIP outgoings can scale organically with your business. To be clear, the headline price doesn’t include calls, which are charged on a pay-as-you-go basis; if you anticipate heavy usage, optional UK or EU add-on call packages can be added, with prices starting at £44.95 per month. 

Another extra to consider is the £20 porting service, which migrates your existing landline numbers over to your new VoIP account. Alternatively, you can request local, 0845, 0870 and international numbers – or settle for whatever Sipgate assigns to you.

Making the switch isn’t quite instant: you need a “start code” to authorise the process, and for security reasons Sipgate insists on sending this by post. We only had to wait three days for ours, however, during which time we were able to get a head start on configuring our users and phones.

That’s just as well because Sipgate doesn’t offer an import function, which means you’ll need to create each individual user account by hand. It’s not too tedious, though, and whenever a user is registered the system will automatically send them an email with login details for their personal web portal. 

The same applies when it comes to provisioning phones. Sipgate provides plenty of help with this – we were pleased to find clear screenshots showing exactly how to configure our Yealink handsets – but you’ll have to do the actual work yourself. 

With this done, the main web portal offers a handy administration page for quick access to all features. In the customisation section, you can brand the portal by uploading your company logo and providing an MP3 file for hold music, and there are plenty of call-handling features, including forwarding and hunting.

 To use these features you need to set up a user group, which gets its own phone number, voicemail and extension. You can then select whether you want all members’ phones to ring at once, or set them to ring in a specific order after a certain number of seconds has elapsed. For more advanced behaviours, you can configure multiple rules and set the time periods they should be active for. Voicemail and call forwarding can also be applied on a per-user basis with personal rules.

Another way to help callers reach the right person is by setting up an IVR (interactive voice response) service; this add-on feature, starting at £10 per month, can read out a list of up to ten options, to ensure calls are directed to the appropriate extension. You can create your own announcements either by uploading MP3 files, or by using the portal’s Click2Record feature, which lets you use a phone handset to record outgoing messages. Other optional features include group call queuing, presence (so you can see who is calling) and integration with Google’s G Suite.

If you want to take the app route, you should be aware that Sipgate doesn’t offer its own softphones, but the service works happily with a wide range of third-party products. For example, we found Zoiper quick and easy to configure and use on both Windows and iOS.

It all adds up to a hosted VoIP offering that’s well suited to small businesses. Don’t be put off by the manual phone provisioning and user setup – plenty of help is provided, and flexible licensing plans make Sipgate Team very cost-effective too.

Gradwell Wave review: Fuss-free phoning


Dave Mitchell

24 Mar, 2020

Easy deployment and great call features make this a likeable cloud VoIP service – and it’s good value

Price 
£10 exc VAT

UK-based Gradwell has been in the business communications market for over 20 years, and at the end of 2019 it launched its own cloud-hosted VoIP service. Wave has been designed from the ground up to address the needs of busy SMBs: it’s simple to deploy, easy to manage and packed with call-handling features, while offering per-user pricing that’s ideal for growing businesses.

Wave is hosted on Amazon Web Services (AWS), so it offers good reliability and can scale easily to cope with heavy demand. And in case you’re worried about having all your eggs in one basket, be assured that Gradwell has deployed Wave across two different AWS sites as protection against unplanned outages.

Costs are easily managed: there are three Wave packages to choose from, which include different numbers of monthly call minutes to landlines and mobiles. The cheapest package is Wave 100, which costs £10 per user per month and includes 100 minutes of calls. Obviously that will cover only very light usage; if you need more, Wave 1000 starts at £13 and allows 1,000 minutes, while Wave 3000 costs from £18 and offers, you’ve guessed it, 3,000 minutes.

When you’re ready to sign up you can expect a personal service, with a Gradwell agent on hand to talk through your needs and help you pick a call package and choose phone numbers. Very little technical knowledge is required: Gradwell offered to handle the process of porting over our existing numbers, and creating a base set of users for us. To make sure we hit the ground running, the company also assigned a personal agent to take us through a detailed on-boarding session.

If you need them, Gradwell can even supply your VoIP handsets. Wave is currently geared up for Yealink phones, and we’ve no complaints about that as it’s the brand we choose for our own testing. A good range of models is on offer, from the basic T19 up to the slick CP960 conference phone. We went for T42S desk phones, and found that provisioning was almost a non-issue, as by the time they reached our offices their MAC addresses had already been added to our portal. All we had to do was connect the phones to our network, assign them to users and reboot and we were ready to go.

For those who prefer the soft approach, Gradwell has also created mobile apps for Android and iOS. We tried the iOS version on an iPad and were impressed by how easy it was to connect to a user’s account: all we had to do was enter the right username and password, or scan in a QR code from the user portal. There’s also a browser-based softphone for Google Chrome, which can be used to make calls, receive desktop notifications for incoming calls, create an address book and record calls to local storage.

Wave doesn’t currently offer users their own personal portal, but the administrative console contains all the user and phone-management tools you’d expect, along with a wealth of call-handling features. Hunt groups are easy to create: you simply pick an extension, then define a series of steps determining where to route calls if they go unanswered.

There’s also a good spread of features that some providers charge extra for. A flexible call queuing system includes options for advising that calls will be recorded, playing hold music and presenting reassuring messages to ensure callers don’t hang up. Voice menus are just as versatile, as you can record voice prompts from a phone or by uploading a WAV file to the portal. Calendar routes redirect calls during specified date periods (such as weekends or bank holidays), calls can be routed according to caller ID and pickup groups can be defined so that colleagues can answer other users’ phones.

If you’re looking for the smoothest possible transition to VoIP, Wave has you covered. It’s very easy to set up and manage and offers plenty of features for the price, making it a great fuss-free VoIP solution.

Five key takeaways from RSA Conference 2020: Cloud SIEM, Zero Trust, API-based security, and more

Bottom line: Passwordless authentication, endpoint security, cloud-native SIEM platforms, and new API-based data security technologies were the most interesting tech developments, while keynotes focusing on election security, industrial control systems’ vulnerabilities and the persistent threat of state-sponsored ransomware dominated panel discussion.

This year’s RSA Conference was held February 24 to 28 in San Francisco’s Moscone Center, attracting more than 36,000 attendees, 704 speakers, and 658 exhibitors unified by the theme of the human element in cybersecurity. The conference’s agenda is here, with many session recordings and presentation slides available for download.

Before the conference, RSA published the RSAC 2020 Trend Report (PDF, 13 pp., no opt-in). RSA received 2,400 responses to their call for speakers and based their report on an analysis of all submissions. The 10 trends in the RSAC 2020 Trend Report are based on an analysis of all papers submitted to the conference. It’s a quick read that provides a synopsis of the main themes of the excellent sessions presented at RSAC 2020.

The following are the five most interesting takeaways from the 2020 RSA Conference:

Endpoint security products dominated the show floor, with over 120 vendors promoting their unique solutions

There were over 50 presentations and panels on the many forms of endpoint security as well. Instead of competing for show attendees’ attention on the show floor, Absolute Software took the unique approach of completing a survey during RASC 2020. Absolute’s team was able to interview 100 respondents, with most holding the position of a manager/supervisor or C-level executive. 

More than three in four respondents reported their organisations are using endpoint security tools, multi-factor authentication, and employee training and education to protect data, devices, and users. You can review their survey results here.

The number of vendors claiming to have Zero Trust solutions grew 50% this year, from 60 in 2019 to 91 in 2020

There continues to be a lot of hype surrounding Zero Trust, with vendors having mixed results with their product and messaging strategies in this area. A good benchmark to use for evaluating vendors in the Zero Trust market is the Forrester Wave: Zero Trust eXtended Ecosystem Platform Providers, Q4 2019, written by Chase Cunningham and published on October 29, 2019. I’ve summarised the lessons learned in the post, What’s New on the Zero Trust Security Landscape In 2019.

Over 30 vendors claimed to have passwordless authentication that met the current FIDO2 standard

In keeping with the theme of this year’s RSA Conference of Human Element, vendors offering passwordless authentication were out in force. Centrify, Entrust Datacard, HID Global, Idaptive, ImageWare, MobileIron, Thales, and many others promoted their unique approaches to passwordless authentication, leveraging the FIDO2 standard.

FIDO2 is the latest set of specifications from the FIDO Alliance, an industry standards organisation that provides interoperability testing and certification for servers, clients, and authenticators that meet FIDO2 specifications. I’ve written a separate post just on this topic, and you can find it here: Why Your Biometrics Are Your Best Password.

Cloud-based security information and event management (SIEM) systems capable of integrating with third party public cloud platforms reflect the maturity nature of this market

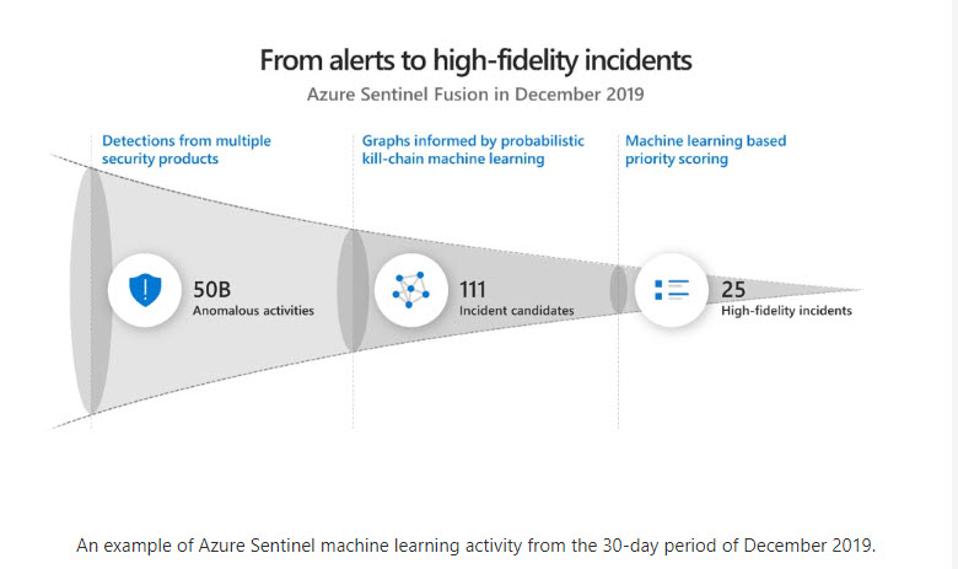
Of the several vendors claiming to have cloud-based SIEM, Microsoft’s Azure Sentinel’s demo showed in real-time how fusion AI technology can parse large volumes of low fidelity signals into a few important incidents for SecOps teams to focus on. Microsoft said that in December 2019 alone, Azure Sentinel evaluated nearly 50 billion suspicious signals, isolating them down to just 25 high-confidence incidents for SecOps teams to investigate. The following graphic explains how Azure Sentinel Fusion works.

Five Interesting Takeaways From RSA Conference 2020

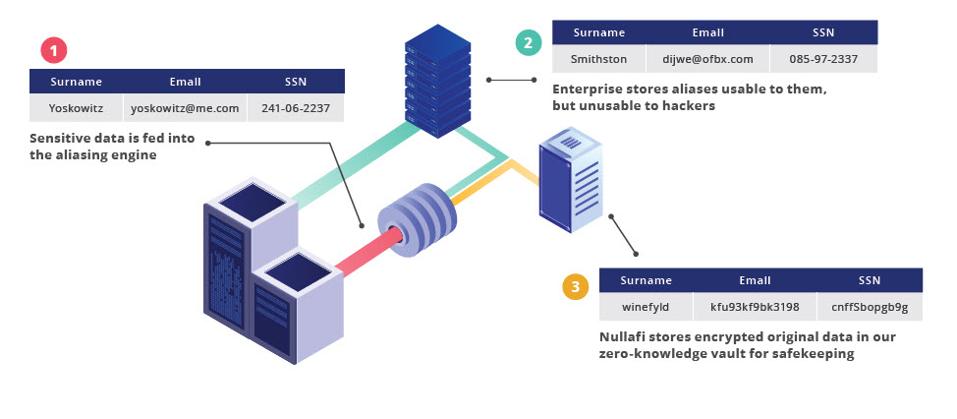
One of the most interesting startups at RSA was Nullafi, who specialises in a novel API-based data security technology that combines data aliasing, vaulting, encryption, and monitoring to create an advanced data protection platform that makes hacked data useless to hackers

What makes Nullafi noteworthy is how they’ve been able to build a data architecture that protects legacy and new infrastructures while making the original data impossible for a hacker to reverse engineer and gain access to. It desensitises critical data so that it’s useless to hackers but still useful for an organisation to keep operating, uninterrupted by a breach to your business. Nullafi is built to AWS GovCloud standards.

The Nullafi SDK encrypts the data before sending it to the Nullafi API. It then re-encrypts the data within their zero-knowledge vault in the cloud (or on-premises). The result is that no sensitive data in any format is shared with Nullafi that could be used or lost, as their architecture doesn’t have visibility into what the actual data looks like. The following graphic explains their architecture:

Five Interesting Takeaways From RSA Conference 2020

Main picture credit: Louis Columbus

https://www.cybersecuritycloudexpo.com/wp-content/uploads/2018/09/cyber-security-world-series-1.pngInterested in hearing industry leaders discuss subjects like this and sharing their experiences and use-cases? Attend the Cyber Security & Cloud Expo World Series with upcoming events in Silicon Valley, London and Amsterdam to learn more.

Dame Jayne-Anne Gadhia steps down as Salesforce UK lead


Daniel Todd

17 Mar, 2020

Dame Jayne-Anne Gadhia has stepped down from her role as Salesforce’s UK Chief Executive, calling time on the former Virgin Money boss’ brief six-month stint in the job.

Announcing the change, the US software giant said Gadhia had made the decision to focus on her price comparison startup Snoop, which recently won financial backing from Salesforce’s venture investing division, but will remain as an adviser to the firm.

Paul Smith, executive vice president and general manager for Salesforce UK and Ireland, will now take on the business responsibilities in the region, the company confirmed.

“I would like to thank Jayne-Anne for her vision and passion in leading Salesforce UK and Ireland,” said Marc Benioff, Salesforce CEO. “We look forward to continuing to work with her in her role as a strategic advisor to Salesforce and wish Snoop enormous success.”

Gadhia co-founded Virgin Direct in 1995 and became CEO of Virgin Money back in 2007, spending the next 11 years at the business. She joined Salesforce on 1 October last year, tasked with leading the firm’s UK&I business through the next stage of its growth, and was recognised in the 2019 New Year’s Honours list for her contribution to financial services and women in the finance sector.

As reported by City A.M., Gadhia had turned down a prospective role at the Bank of England to lead Salesforce’s UK arm, following the launch of a $2.5 billion investment programme as part of its commitment to the country.

Gadhia said she will now be focusing her time on comparison start-up Snoop – which has hit the ground running since its inception back in February – but will remain on hand in an advisory role.

“Snoop launched last month and has exceeded our highest expectations in all respects,” she commented. “As a result, I am delighted to be able to focus my efforts on making Snoop an enormous success and on making all of our customers better off.

“My thanks go to Salesforce and to Marc Benioff for supporting me in this decision. I look forward to working with both Marc and Salesforce in a senior advisory role.”

The development follows the recent promotion of former BT chief executive Gavin Patterson to the role of president and chief executive of Salesforce International.

Dame Jayne-Anne Gadhia steps down as Salesforce UK lead


Daniel Todd

17 Mar, 2020

Dame Jayne-Anne Gadhia has stepped down from her role as Salesforce’s UK Chief Executive, calling time on the former Virgin Money boss’ brief six-month stint in the job.

Announcing the change, the US software giant said Gadhia had made the decision to focus on her price comparison startup Snoop, which recently won financial backing from Salesforce’s venture investing division, but will remain as an adviser to the firm.

Paul Smith, executive vice president and general manager for Salesforce UK and Ireland, will now take on the business responsibilities in the region, the company confirmed.

“I would like to thank Jayne-Anne for her vision and passion in leading Salesforce UK and Ireland,” said Marc Benioff, Salesforce CEO. “We look forward to continuing to work with her in her role as a strategic advisor to Salesforce and wish Snoop enormous success.”

Gadhia co-founded Virgin Direct in 1995 and became CEO of Virgin Money back in 2007, spending the next 11 years at the business. She joined Salesforce on 1 October last year, tasked with leading the firm’s UK&I business through the next stage of its growth, and was recognised in the 2019 New Year’s Honours list for her contribution to financial services and women in the finance sector.

As reported by City A.M., Gadhia had turned down a prospective role at the Bank of England to lead Salesforce’s UK arm, following the launch of a $2.5 billion investment programme as part of its commitment to the country.

Gadhia said she will now be focusing her time on comparison start-up Snoop – which has hit the ground running since its inception back in February – but will remain on hand in an advisory role.

“Snoop launched last month and has exceeded our highest expectations in all respects,” she commented. “As a result, I am delighted to be able to focus my efforts on making Snoop an enormous success and on making all of our customers better off.

“My thanks go to Salesforce and to Marc Benioff for supporting me in this decision. I look forward to working with both Marc and Salesforce in a senior advisory role.”

The development follows the recent promotion of former BT chief executive Gavin Patterson to the role of president and chief executive of Salesforce International.

Microsoft Teams goes down at start of mass remote working


Bobby Hellard

16 Mar, 2020

Microsoft Teams went down across Europe for two hours on Monday, causing mass frustration for the many remote workers now increasingly dependent on the service.

Users experienced issues signing into the service and also trouble sending messages. 

Although Microsoft managed to fix the problem within two hours, the timing could not be worse as millions of people across the country began remote working amind the outbreak of COVID-19. 

As users from various European countries began reporting issues, Microsoft tweeted that it was looking into the problem.

«We’re investigating messaging-related functionality problems within Microsoft Teams. Please refer to TM206544 in your admin centre for further details,» the company said. 

This is the second major outage to hit Microsoft in as many years after Office 365 went offline in 2018. There is a suggestion that Monday’s faults could be due to more people using the services as businesses encourage workers to stay home.

Just a week ago, Microsoft offered a six-month free trial for Teams, according to Businesses Insider, to help those soon to be self-isolating. Google has also offered up parts of its remote working services in a bid to work around the coronavirus outbreak. 

Microsoft’s outage is a poor start to what could be a big opportunity for cloud computing.

With mass remote working and many business events going «virtual», video linkups, VR and other similar technologies will become a crucial element of everyday life. 

Outages and service disruptions are common occurrences with new technologies, but as the world begins what looks like a prolonged period of self-isolation, it’s these kinds of services that will keep many industries ticking along.

Add to that, the need for us all to stay connected to one another during a pandemic and Microsoft Team’s and services like it have suddenly become vital. 


IDC finds how organisations investing in cloud-based quantum computing seek to gain competitive edge

IDC, in its recent study titled ‘Quantum Computing Adoption Trends: 2020 Survey Findings’ has found that organisations currently investing in cloud-based quantum computing technologies are expecting to see improved AI capabilities, accelerated business intelligence, and increased productivity and efficiency.

During its initial stage, the study indicated that as cloud-based quantum computing is still at its nascent stage and the allotted funding for its initiatives is limited – somewhere between 0%-2% – the end-users are very much positive that they will realise a competitive advantage owing to early investment. At present, the manufacturing, finance, and security industries are at the forefront as they are experimenting with more potential use cases, developing advanced prototypes, and implementing the technology.

Limited skills, lack of available resources, complex technology, and cost are some of the factors that discourage some organisations from investing in quantum computing. However, these strands, combined with a large interdisciplinary interest, have compelled vendors of quantum computing to develop the technology that addresses multiple end-user needs and skill levels.

Last year, researchers at Google claimed that their quantum computer has solved a problem in some minutes that would otherwise take even the very best conventional machine thousands of years to crack. They termed this milestone as ‘quantum supremacy’, as it took a very long time to realise the immense potential of quantum computers. On the other hand, IBM has criticised the claim stating that the same problem can be solved by its machine in 2.5 days with sophisticated classical programming, arguing that Google has not yet reached the milestone in actuality. 

https://www.cybersecuritycloudexpo.com/wp-content/uploads/2018/09/cyber-security-world-series-1.pngInterested in hearing industry leaders discuss subjects like this and sharing their experiences and use-cases? Attend the Cyber Security & Cloud Expo World Series with upcoming events in Silicon Valley, London and Amsterdam to learn more.

What is cyber insurance truly worth? Analysing the risks and responses

Analysis Cyber risk has overtaken financial risk as the greatest threat that we all face, according to PwC’s 2019 global crisis survey. There are also concerning parallels between the global financial crisis of 2009, and the current cyber threat landscape

The question is, to what extent is cyber insurance the answer?

Currently most companies don’t have any cyber insurance. Coverage is only 40% in the US, and 10% in the UK. Elsewhere, it’s even lower. Many cyber insurers boast that they can provide an insurance quote in under an hour. If they are able to provide cover for such a complex policy in such a short period of time then this should ring alarm bells. You should be concerned with their ability not only to accurately assess your risk position, but also to price the policy accurately.

Some insurers base their risk assessment on cyber security risk ratings. Some of these ratings are produced by firms that use web crawlers that check externally facing endpoints for known vulnerabilities. This is a fairly crude method, but it’s probably still the best way to address the mass market at low cost. The problem is, it’s a bit like evaluating fire-safety risk by looking at a photograph of a building taken from across the street. You can get an idea of the building’s shape and size, but you can’t tell if there’s flammable material inside, or if the building is equipped with fire alarms, or sprinkler systems. A photo like this is better than nothing; but it still provides only a basic, limited idea of the real risk.

The reason that some insurers can probably afford to base premiums on such crude risk metrics is that cyber insurance policies often include a host of provisions and exclusions that in effect make it impossible to claim for almost any incident of any kind. If they want to refuse to pay out, they're probably going to find a way of justifying this. Indeed almost the only reason they would pay out at all is to encourage other clients to sign up.

So if there is a global cyber crisis they may well refuse to pay out on any policies and consider withdrawing from the market entirely.

Examples of common cyber insurance terms or exclusions are as follows:

  • Policies tend to only cover 'a hacker who specifically targets you alone'. Unfortunately, cyberattacks are rarely focused on a single victim. Often either the same attack vector is used on many victims in a scattergun approach (phishing attacks) or malware is used that is contagious in nature (WannaCry)
     
  • Policies tend not to cover 'any failure…by a cloud/infrastructure provider…unless you own the hardware and software'. Unfortunately, this would not only exclude almost all cloud use, but also exclude almost anything other than hosted services which exclusively use kit you own
     
  • Policies tend not to cover incidents involving a 'third party…not unduly restricted or financially limited by any term in any of your contracts'. This is meant to ensure that the insurer is able to pursue any third party involved for unlimited damages. Unfortunately, this excludes almost all service providers as they themselves tend to specify some limitation to damages in their contracts, such as damages being limited to the value of the contract. No service providers these days offers unlimited liability
     
  • Policies tend not to cover incidents involving 'any individual hacker within the definition of you'. Unfortunately, this would exclude all insider threats
     
  • Policies tend not to cover 'the use by you of any software or systems that are unsupported by the developer'. This clause rarely specifies that the unsupported software needs to be part of the attack vector, which means that you could be excluded if you had a single instance of something like Windows XP on your technology estate, even if this was not part of the attack at all
     
  • Policies tend not to cover incidents 'attributable to any failure…by the Internet Service Provider (ISP) that hosts your website, unless such infrastructure is under your operational control'. Unfortunately, this would exclude all incidents involving any ISP as it is unheard of for ISP infrastructure to be under your operational control
     
  • Policies tend not to cover 'acts of foreign enemies, terrorism, hostilities or warlike operations (whether war is declared or not)'
     
  • Policies tend not to cover 'any error or omission arising out of the provision of negligent professional advice or design'. Unfortunately, if at any time you have tested or assessed your security (as is required under GDPR), but then failed to implement all the resulting recommendations then your cover could be void. So, if you have had penetration testing or certification audits (for ISO 27001 or PCI say) then you need to address every single recommended revision or recommendation or you risk voiding your cover
     
  • Policies tend not to cover 'anything likely to lead to a claim, loss or other liability under this section, which you knew or ought reasonably to have known about before we agreed to insure you'. This is the pre-existing condition provision. This means that if in any business case that your team make for adopting cyber insurance, you cite potential vulnerabilities as reasons for this adoption, then these very vulnerabilities could then be excluded from any cover

For these reasons we have already seen that some claims are not being paid. For example, several major insurers have declined to pay for damages caused by the NotPetya ransomware attack a few years ago. They say it was a “hostile or warlike action” and therefore not covered.

On top of this other claims have only been paid in part. For example, Norsk Hydro received an insurance payout of $3.6 million. That’s only about 6% of the overall damage that was estimated to be as much as $71 million. It covered the cost of the technical fix, but that was it.

Cyber insurance, while important, simply isn’t a substitute for prevention or for crisis preparedness. You need to have all three.

Here are a few measures to consider:

We need increased adoption of cyber insurance cover, with organisations being far more discerning about the policies they adopt:

  • Clients need to understand their risk appetite – you could spend an almost infinite amount on cybersecurity, but you don’t necessarily need to do so
     
  • They need to be far more aware of the exclusions in the policies on offer and to base their choice on the nature of the cover rather than purely on price – there’s no point in paying for a cheap policy that won’t pay out
     
  • They need to choose policies that are appropriate for their business and for their risk position – specialist brokers can help you find a policy that is right for you
     
  • They also need to consider separate specialist incident response cover if this is not included in their cyber insurance policy (most don’t include it) – while an elite team could save you from disaster, the wrong team won’t just fail to fix the problem, they could actually make it worse

What we tend to find is those organisations who have incident response cover tend to call in the experts straight away, while those without it often attempt a DIY fix before calling for help. By the time they do call for help though it’s often too late – the impact and exposure have magnified significantly – and they call in the wrong people, not having time to accurately select the right experts.

Almost worse than a policy that won’t pay out is one that won’t provide top quality incident response. Whether your insurer is footing the bill or you are, here’s what you will really need:

  • The technical fix: Get expert help from a specialist security response team to identify and the fix problem(s), and do forensics to diagnose the cause and full scope. Getting an immediate fix to resolve the problem, stem any data loss and recover any systems is essential. Any delay will magnify the impact of the incident and damages incurred
     
  • The legal defence: Seek expert advice in cyber and data law to rapidly develop a legal strategy and a legally defensible narrative based on the forensics. Having the right legal strategy and narrative are both essential to limit legal and regulatory exposure
     
  • The brand defence: Get expert cyber comms support to help your internal and agency teams deal with the added complexity and enhanced comms workload. The standard PR approach to crisis management simply won’t work in a cyber incident and may even make things worse
     
  • Social response: Get top global privacy/security influencers to act as trusted voices to counter misinformation with authority and hysteria with reach and credibility. To counter misinformation and hysteria when your own credibility is at an all-time low, you’ll need the support of authoritative opinion leaders in privacy and security

Part of the reason that you need specialists is the fact that traditional crisis tactics don’t work in a cyber crisis.

In a conventional crisis, you need to understand that with most crises or crimes, the criminals get the blame and the company and customers are seen as victims. The conventional PR tactics in a crisis scenario are to contain any issue until it becomes public and then to show empathy for your customers in order to gain sympathy from the press and general public for both you and the clients. It tends to work well.

A cyber incident is different. You’re likely to be on the back foot: a cyber incident could well be public before you even become aware yourselves. What’s more, cyber incidents aren’t instantaneous: the average breach occurs long before it is detected.

Unfortunately, cybercrime is about the only crime where the victim gets the blame. However much you spent on cybersecurity, the press and public will blame you and not the hackers. You need to be prepared to face the regulators, a hostile press and inevitable hysteria and misinformation.  Containment is not possible due to GDPR disclosure obligations and showing empathy won’t gain you any sympathy. It’ll simply put your executives in the firing line.

Crisis preparedness is also critical. Scenario planning and realistic simulation exercises are essential for preparedness, and indeed testing and assessment are mandated under GDPR. So if companies don’t do it, and they then have an incident – the regulatory action will be far harsher.

For companies of any size, it’s probably not a matter of ‘if’ they’ll get hit, but ‘when’. And since the average breach takes more than six months to detect, it may well already have happened.

If ever there was a time to make a case to the board for the need for cyber insurance and crisis preparedness, it is now – with a looming pandemic. The last crisis may have been financial, the current one may be health related, but the chances are that the next one with be a cyber crisis. We all need to be prepared for this.

https://www.cybersecuritycloudexpo.com/wp-content/uploads/2018/09/cyber-security-world-series-1.pngInterested in hearing industry leaders discuss subjects like this and sharing their experiences and use-cases? Attend the Cyber Security & Cloud Expo World Series with upcoming events in Silicon Valley, London and Amsterdam to learn more.

The cloud news categorized.